Follow with Edit this page on Go back to the Bliki index
Europrogramming: From Eurotheory to Practice
By Fabrizio Montesi.
Created on 2026-09-16.
Last updated on 2026-09-16.
Some of the growing infrastructure behind Europrogramming: Lean, Mathlib, and CSLib.
Europrogramming is the practice of developing software with formal methods so that programs, specifications, and machine-checkable evidence about their behaviour are part of the same process. The practice is not new. I started using Europrogramming in recent conversations to refer to something that has been taking shape for a long time, but is now rapidly assuming a new scale.
The name comes from Eurotheory, the somewhat peculiar label for a tradition in theoretical computer science concerned with formal models, logic, programming languages, semantics, and verification. I mean Europrogramming somewhat tongue-in-cheek, but also as a homage to the gargantuan amount of free research behind that tradition. Europrogramming is what happens when that mathematical discipline becomes embedded in programming practice.
Timing is relevant here. AI-assisted coding is surpassing our capacity to manually read and understand code. The sheer speed and volume of software generation are simply becoming too great for human inspection and testing to remain our primary means of assurance. This demands new ways to retain human agency, control, and understanding as software grows in scale and complexity.
The promise of Europrogramming is to develop software together with precise specifications of what it should – and should not – do, and machine-checkable evidence that those specifications are met. Proof assistants are particularly powerful environments for this, because programs, specifications, and proofs can inhabit the same formal language.
None of this appeared overnight. Europrogramming rests on decades of free, fundamental research and on the extraordinary execution that turned mathematical ideas about computing into languages, proof assistants, libraries, and tools. Before looking forward, it is worth reflecting on where that came from.
From Eurotheory to Europrogramming
I encountered the term Eurotheory only years after entering research. I think I first heard it from an algorithms researcher. It felt weird, as if the name had been invented to mark a divide: there was theory, meaning algorithms and complexity, and then there was the other theory (Eurotheory).
Vardi [2015] discussed this distinction nicely in an opinion piece for the Communications of the ACM, referring to the classic division in the Handbook of Theoretical Computer Science: Volume A, Algorithms and Complexity, and Volume B, Formal Models and Semantics. European theoretical computer science traditionally cast a wider net over both.
The Euro in Eurotheory has always felt odd to me. Many giants of Eurotheory I knew of had worked outside Europe, and its communities were clearly international. But what I found truly ridiculous was learning that, as Vardi recounts, Eurotheory had sometimes been used derogatorily, to suggest research that was narrow, esoteric, or too detached from practice. How is pursuing a deep mathematical understanding of logical reasoning, programming, semantics, system modelling, and software construction not relevant?
While I found this ridiculous, I did not find it particularly surprising. Drawing oppositions between research areas is an old and unfortunate labelling exercise, often entangled with research policy and funding, much like the traditional divide between pure and applied research. These boxes can serve us poorly. A researcher interested in both theory and practice might describe themselves as ‘jumping’ between pure and applied research, but this activity often feels much more continuous than such a hopping metaphor suggests.
I enjoyed reading Stokes' Pasteur's Quadrant [1997] precisely because it unfolds a different way of thinking about this. Stokes challenged the idea that basic and applied research sit at opposite ends of a single spectrum. Instead, he treated the pursuit of fundamental understanding and the consideration of practical use as separate dimensions. His famous example was Pasteur himself: research can simultaneously seek deep understanding and be inspired by problems of use. Stokes called this use-inspired basic research. That framing feels much closer to home.
Eurotheory asks questions such as: What does a program mean? How can we describe its behaviour mathematically? What can one process observe about another? When are two programs equivalent? Which properties can a programming language guarantee by construction? How can we state what a system is supposed to do – or must not do – and prove that it actually respects those requirements?
These are deeply theoretical questions with deeply practical consequences. In a world run by software, we should seek to understand software as deeply as mathematics allows.
Eurotheory has hardly been an ivory-tower exercise. Decades of work in formal methods and mathematically grounded languages have produced pioneering technology for software assurance. Communities around proof assistants (tools for writing and automatically checking the validity of proofs) like Rocq, Agda, Isabelle, and many other systems have demonstrated what can be achieved when specification, programming, and proof are brought together. Formal methods have influenced type systems, compilers, security, distributed systems, language design, and much of the programming technology we now take for granted.
Landmark projects have already shown how far this can go, with fantastic results for real-world software. For example, CompCert [Leroy et al., 2016] demonstrated that even a sophisticated optimising compiler can come with machine-checked proofs of correctness; seL4 [Klein et al., 2009] developed a low-level operating system with strong formal guarantees. Formal methods are already the gold standard when unusually high assurance is needed.
What is changing is not whether these ideas can work. Rather, it is the scale and scope at which we need them now.
AI has come to build... and break things
AI can now write useful code. Sometimes it is remarkably useful. Sometimes it is remarkably annoying.
Anyone who has spent serious time programming with an AI assistant knows the new experience: producing code has become easier, but understanding it still takes time. In the ultra-rapid AI-assisted development cycle, I spend most of my time reading and observing, not prompting.
In a world where machines write quickly and humans audit slowly, AI-assisted programming can be surprisingly tiring. AI is moving the bottleneck of software construction from code generation to establishing and maintaining confidence in the software being produced.
At a time when software generation outpaces human comprehension, formal methods offer something incredibly valuable: they can shift part of the burden of assurance from manually inspecting code to checking evidence about the code.
There is another side to this urgency. AI has become remarkably capable at finding vulnerabilities. There is an important asymmetry here, familiar to many computer scientists: a single counterexample can be enough to demonstrate that a system is vulnerable, whereas establishing the absence of a class of vulnerabilities requires reasoning about all relevant behaviours.
We need to equip ourselves with stronger programming methods, or we will soon face concrete risks for our digital infrastructures. And whatever methods we decide to use, they need to scale with the amount of software being produced.
Ask AI to Europrogram
Mathematics has already demonstrated how this can work. The Lean community has built a proof assistant and programming language around which a remarkable ecosystem is developing. The Mathlib library contains a large and carefully curated body of machine-checked mathematics.
This is where great execution flexes its muscles. Mathlib is a huge collective effort, and the Lean community has supported it with remarkable purpose.
AI systems that use Lean and Mathlib to train or check their reasoning have already achieved striking results in mathematical reasoning. Developments are proceeding at breakneck speed, so the next examples may become outdated very soon: building on previous efforts, Anthropic reported that Claude had produced a complete Lean formalisation of Fermat's Last Theorem; not much later, OpenAI reported an AI-generated proposed solution to the Navier–Stokes Millennium Prize Problem developed with AI, together with a formalisation in Lean.
The striking part about these results is not just the results themselves. It is that they prove that this division of labour can be effective: AI produces a formal development, and Lean checks it. This is inspiring people to go from asking the AI
Write this program.
to asking, instead,
Write this program and a machine-checkable proof that it satisfies these specifications.
In other words, ask the AI to Europrogram.
The point is to put code generation on mathematical rails. New companies are appearing around this intersection, including Logical Intelligence, Harmonic's Aristotle, and Latinum.AI. Established technology companies and research laboratories are investing heavily in formal reasoning as well.
The interesting question is therefore becoming less whether AI and formal methods can work together, and more what we should ask them to prove.
What can we actually do with Europrogramming?
The sudden, enormous interest in formal methods and their combination with generative systems is exciting. But it is important that we understand what the opportunity actually is. Formal verification is not magic: a proof establishes a mathematical statement, and that statement is exactly what we can rely on.
It is therefore essential that we choose statements carefully. We might have proven that an application is memory safe, but maybe it leaks private data through the network. A software can be functionally correct, but might consume too much energy. A distributed application might be deadlock-free, but gets authorisations from the wrong actors.
These guarantees are all valuable. My point is emphatically not that any of them matters less. The point is that we must not let what is convenient to verify determine what is worth verifying.
If Europrogramming is to become a general programming practice, it must grow not only in scale, but also in scope. We need to become capable of specifying and verifying a much broader range of properties – including properties that may be difficult to express with the formalisms and tools we have today.
That raises two major challenges. One is technical: building the formal infrastructure needed to express and reason about such a broad range of properties. The other is about relevance: deciding which properties are actually worth guaranteeing.
The first is a fundamental computer science problem. The second cannot be solved by computer science alone.
Infrastructure: the ‘rails’
The first challenge calls for infrastructure.
Applying Europrogramming at scale requires a rich and integrated formal vocabulary for talking about software, together with strong methods for verifying software against this vocabulary. This is harder than it sounds.
Computer science has developed an extraordinary variety of models, logics, programming languages, specification techniques, and notions of correctness. We know how to reason about functional correctness, time and space complexity, information flow, concurrency, resources, failures, adversaries, knowledge, probability, and much more.
However, these theories often live in different worlds. A verification project may therefore spend substantial effort rebuilding the concepts it needs before it can even state the property it ultimately cares about. The same definitions and theorems are formalised repeatedly, sometimes in subtly incompatible ways. This is expensive for humans, makes results difficult to reuse, and provides a fragmented foundation for AI.
This is one motivation behind the CSLib open source project, where I serve as lead maintainer [Barrett et al., 2026; Henson and Montesi, 2026]. Our ambition is to build a shared, machine-checked body of computer science in Lean: algorithms, data structures, models of computation, logics, semantics, verification infrastructure, and verified software, designed so that results from different areas can be connected and reused.
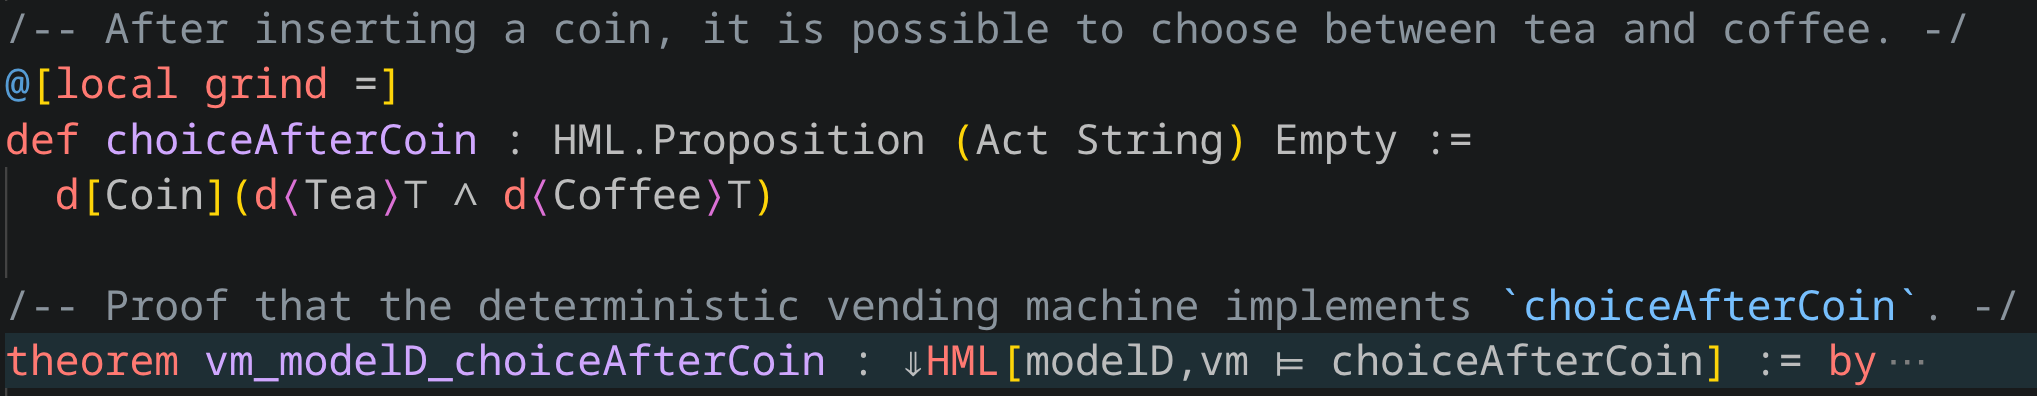
Proof that a simple vending machine satisfies a behavioural specification: after inserting a coin, the user can choose between tea and coffee. The example uses CSLib's reusable APIs for labelled transition systems and Hennessy–Milner Logic.
CSLib is inspired by Mathlib's success. Mathlib is much more than a repository of theorems. It gives mathematicians and AI systems a common language in which definitions and results from different areas can be stated, checked, connected, and reused. Computer science needs something similar.
Different research communities develop their own notation, terminology, conventions, and implicit ways of presenting ideas. Learning a neighbouring field often requires learning this internal language before one can even get to the underlying concepts.
A shared formal language changes that in an interesting way. Once definitions from different communities are expressed in the same proof assistant, many superficial differences begin to fall away. One can inspect the exact definition of a concept, follow its dependencies, see which assumptions a theorem actually uses, and try to connect it to ideas somewhere else. In CSLib, it has been thrilling to establish connections across domains such as concurrency theory, automata, computability, complexity, and logic. This is also changing how I work. More and more, I find myself reading Mathlib source code when I want to understand something outside my immediate expertise, simply because everything eventually boils down to Lean code.
I increasingly think of libraries like Mathlib and CSLib as a kind of universal literature. They do not replace papers, textbooks, or human explanation. But they add a common representation of knowledge that humans can study, machines can check, and both can build upon.
This matters enormously for Europrogramming. If we want AI to produce software together with meaningful evidence about its behaviour, then we need a rich formal world in which those properties can be expressed and connected. These are the technical ‘rails’.
Verification is only as good as the specification
Here is the other, perhaps trickier challenge.
Even if we become extraordinarily good at proving that software satisfies specifications, somebody still has to decide which specifications matter.
That is not a purely technical question. Suppose, for example, that we want a social platform to provide a guarantee that the ranking of news does not depend on its estimate of a user's political preference. We might formalise this by requiring the ranking to remain invariant when the inferred political preference changes while other permitted inputs remain fixed (for which we need the rich language we talked about previously).
That gives us something precise to verify, but it also raises other questions. Which inputs are permitted? Could some of them act as proxies for political preference? Is this guarantee actually useful to users? Would it produce the social effect we intended? How should the guarantee be explained to people and institutions? Under what assumptions should somebody rely on it?
A theorem prover cannot answer these questions for us. This is why I think the next phase of formal methods must involve much deeper collaboration with the social sciences, humanities, law, and other domains. At FORM, the Centre for Formal Methods and Future Computing, this is becoming an increasingly important part of how we think about the future of software. Formal methods can give us extraordinarily strong evidence that a precisely stated property holds. But deciding which properties correspond to human needs, institutional requirements, social values, or meaningful forms of control requires expertise well beyond formal methods.
Europrogramming therefore cannot mean taking whatever properties are easiest for us to formalise and merely scaling up their verification. It must also mean expanding the range of questions that our formal methods are capable of asking.
‘Verified’ is not enough
Even if we get all of the above right, a problem remains: communicating what verification actually gives us.
Imagine a future in which software products proudly display a badge: VERIFIED ✓. Sure, but verified for what? With what limitations? And most importantly, what does that actually mean for me as a user?
While a proof is precise, the word verified is not, especially to non-experts. If formal verification becomes merely another label that people cannot interpret, they will quite reasonably learn to ignore it. The value of verification therefore has to be communicated in terms that people and organisations can actually use.
Of course, this does not mean that everybody should learn to read formal proofs. That would not only be unreasonable, but also defeat the very purpose of having machine-readable evidence that can be automatically checked in the first place.
What people and institutions need is actionable information derived from those proofs. There is a profound difference between saying:
This platform is formally verified.
and saying:
This platform does not rank news based on your inferred political preference.
The latter is a claim that somebody can understand, question, compare with alternatives, and potentially act upon. Underneath that claim can sit a precise specification, an implementation, and machine-checkable evidence connecting the two. This is where Europrogramming can connect to human agency. The aim is not simply to produce correct software. It is to create a chain from human intent to formal specification, from specification to software, from software to evidence, and from evidence back to something humans and organisations can understand and use.
Keeping that chain intact may turn out to be one of the defining challenges of programming in the age of AI.
Conclusion
Formal methods are receiving extraordinary attention. With this attention comes responsibility. It would be a wasted opportunity if we merely became dramatically better at proving the same narrow family of properties for dramatically more programs.
The challenge is much, much larger:
- We need to scale formal methods to the quantity of software that humans and AI can produce.
- We need to broaden their scope so that we can express more of the properties that actually matter.
- We need shared formal foundations so that every project does not have to rebuild its own mathematical universe.
- We need collaboration across disciplines so that specifications reflect the concerns of the people and institutions affected by software, rather than only the properties that computer scientists find technically convenient.
- We need to communicate the resulting guarantees in ways that people can understand and act upon.
In other words, Europrogramming is Eurotheory becoming infrastructure, with mathematical understanding becoming an intrinsic part of software construction itself. We should pursue this seriously. Even partial success would teach us a great deal.
AI has come to code, and we are ready – or this is how we become ready.
References
Clark W. Barrett, Swarat Chaudhuri, Fabrizio Montesi, Jim Grundy, Pushmeet Kohli, Leonardo de Moura 0001, Alexandre Rademaker, Sorrachai Yingchareonthawornchai [2026], CSLib: The Lean Computer Science Library.
In CoRR abs/2602.04846.
Full view & info |
PDF |
bibtex
|
doi.org
@article{DBLP:journals/corr/abs-2602-04846,
  author       = {Clark W. Barrett and
                  Swarat Chaudhuri and
                  Fabrizio Montesi and
                  Jim Grundy and
                  Pushmeet Kohli and
                  Leonardo de Moura and
                  Alexandre Rademaker and
                  Sorrachai Yingchareonthawornchai},
  title        = {CSLib: The Lean Computer Science Library},
  journal      = {CoRR},
  volume       = {abs/2602.04846},
  year         = {2026},
  url          = {https://doi.org/10.48550/arXiv.2602.04846},
  doi          = {10.48550/ARXIV.2602.04846},
  eprinttype   = {arXiv},
  eprint       = {2602.04846},
  timestamp    = {Thu, 19 Mar 2026 09:22:46 +0100},
  biburl       = {https://dblp.org/rec/journals/corr/abs-2602-04846.bib},
  bibsource    = {dblp computer science bibliography, https://dblp.org}
}
Christopher Henson, Fabrizio Montesi [2026], Computer Science as Infrastructure: the Spine of the Lean Computer Science Library (CSLib).
In CoRR abs/2602.15078.
Full view & info |
PDF |
bibtex
|
doi.org
@article{DBLP:journals/corr/abs-2602-15078,
  author       = {Christopher Henson and
                  Fabrizio Montesi},
  title        = {Computer Science as Infrastructure: the Spine of the Lean Computer
                  Science Library (CSLib)},
  journal      = {CoRR},
  volume       = {abs/2602.15078},
  year         = {2026},
  url          = {https://doi.org/10.48550/arXiv.2602.15078},
  doi          = {10.48550/ARXIV.2602.15078},
  eprinttype   = {arXiv},
  eprint       = {2602.15078},
  timestamp    = {Sun, 29 Mar 2026 14:38:05 +0200},
  biburl       = {https://dblp.org/rec/journals/corr/abs-2602-15078.bib},
  bibsource    = {dblp computer science bibliography, https://dblp.org}
}
Jan van Leeuwen (Editor) [1994], ‘Handbook of Theoretical Computer Science’, MIT Press. ISBN: 9780262220408.
Xavier Leroy, Sandrine Blazy, Daniel Kästner, Bernhard Schommer, Markus Pister, Christian Ferdinand [2016], ‘CompCert – a formally verified optimizing compiler’, in Proceedings of ERTS 2016.
Gerwin Klein, Kevin Elphinstone, Gernot Heiser, June Andronick, David Cock, Philip Derrin, Dhammika Elkaduwe, Kai Engelhardt, Rafal Kolanski, Michael Norrish, et al. [2009], ‘seL4: Formal verification of an OS kernel’, in Proceedings of ACM SIGOPS 2009, ACM.
Donald E. Stokes [1997], ‘Pasteur's Quadrant: Basic Science and Technological Innovation’, Brookings Institution Press. ISBN: 9780815781776.
Moshe Vardi [2015], ‘Why Doesn’t ACM Have a SIG For Theoretical Computer Science?’, Communications of the ACM. DOI: 10.1145/2791388. Link: https://cacm.acm.org/opinion/why-doesnt-acm-have-a-sig-for-theoretical-computer-science/